Editing of EPUB files - Mass correction - Removal of mid-word breaks

Is there a tool that will perform a task that is similar to spellcheck, but is only looking for mid-word breaks and prompt for correction (optional skip manual approval)?

For example, if a word in the text is found to be

excel lence

when that should be

excellence

it would flag or identify that word for the stripping of the mid-word space (or spaces or tabs or newlines).

I don’t know if tools that look at defined “breakpoints” in words could identify the words that have such “breaks” that should be removed or “healed”?

Does such a tool exist?

Hey @ericmarceau,

I’m not trying to speak as an expert in this response, but as (hopefully) a pointer in a helpful direction. TL;DR: I wasn’t able to find a tool that does exactly what you’re asking (hopefully someone else will).

My initial attempt at looking for a tool, I was able to find a tool called calibre that seems to have some editing capabilities. I installed it, opened up the default epub book that ships with the software, and plugged in your excel lence example (I just picked a random .html file and added the example in, nothing fancy). Then I tried the spellchecker. As expected, it only tried to correct lence to lance. So that doesn’t seem helpful. :frowning:

Calibre does have plugin support, but I wasn’t able to find anything helpful at first glance. Maybe I missed something.

At my current job, I’ve used Natural Language Processing (NLP) by using Python’s Natural Language Toolkit (NLTK) to process customer raised support cases to identify gaps in the knowledge base. In my experience with that project, I had to do quite a bit of spelling checking/word fixing.

Using that angle, I did some googling and ran across this Stack Overflow post with a helpful gist to a Python segmentation script. This functionality seems to both be able to split long strings of characters into words and also remove breaks/spaces between words. I also see that Python has an epub library.

It seems pretty reasonable that a Python script could be put together that handles your functionality for identifying the broken words, offering solutions based on a score, then healing them if you choose to do so.

Maybe some of this information can help you in your search for a tool?

Short answer, no single tool that does exactly that, at least not one I could find. But a few things get close, and honestly the DIY version is tiny.

The reason spellcheck whiffs on this is that hunspell and aspell look at one token at a time. Feed them “excel lence” and they see a real word followed by junk, so you get a squiggle under “lence” with suggestions like “lance” or “fence”. Nothing in there ever considers gluing it back onto the word in front of it. You need something that looks at pairs.

Stuff I found that actually does it:

LanguageTool is probably the best bet off the shelf. It has rules for wrongly split words and it works on token pairs instead of single tokens. Runs local as a server or through languagetool-commandline.jar. English coverage is decent but not complete. German is much better supported, which tracks, since split compounds are basically a national sport over there.

symspellpy has lookup_compound and word_segmentation. Dictionary plus frequency based, and it handles both bad splits and missing spaces. Closest thing to a library that just does your problem.

dehyphen, Python, comes out of the pd3f project. Built specifically for this on text pulled out of PDFs. It scores each join or no join call with a language model instead of a dictionary, so it does better on the ambiguous ones.

pd3f itself if your source is PDFs and you want the extraction pipeline to rebuild paragraphs properly on the way out.

Word and Google Docs will catch some of these in grammar check if it’s a short doc and you just want to eyeball it.

DIY version:

The logic is maybe six lines. Walk adjacent token pairs, and if the joined version is in the dictionary, flag it. Then the filter that kills basically all the false positives: only flag it when the second fragment is not a real word on its own. “excel lence” fires because “lence” is garbage. “may be”, “in to”, “a while” and “all ready” all stay put, and those are exactly the ones a dumb joiner would destroy.

For the approve or skip part, cheapest thing is to dump the candidates and run them through vim with :%s/old/new/gc. That gives you y/n/a/q per match for free. Or build the prompt into the script and add a --yes flag for when you don’t feel like babysitting it.

One thing on scope though. Tabs and newlines are the easy case. A word broken across a line ending, especially with a trailing hyphen, is a different problem than a stray space in the middle of a line, and you’re usually better off fixing that at extraction time than trying to fix it after the fact.

Thank you, Benjamin. What you offered seems to be leaning in the right direction.

I do have both Calibre and Sigil. But their “spelling” functions don’t deal with the scenario I’ve outlined.

Basically, I’ve “picked up” a poorly-reworked version of a book and it is riddled with such broken-word instances.


Those Stack Overflow and gist references were interesting as an awareness of “shotgun” approaches, but I was looking for something with more finesse like the case

  • When being offered an award of excel lence, he was left speachless.

and trying to identify instances of “adjacent” words that should be joined. For that, I don’t know if it requires an overlay of recognition of gradually-built sentence structure, to avoid making some context-based poor joins, but I was hoping that the logic would simply identify possibles for manual confirmation of the join, thereby offering the best of both worlds.

:slight_smile:

Thank you! The dehyphen and pd3f options look like they might be workable … but not for me. I’ve backed away from Python for reasons expressed elsewhere, namely, that the lack of characters delimiting logical code segments have made my every usage a frustrating experience to avoid repetition. Don’t want to go there again! :frowning:

Nonetheless, thank you for bringing those to my attention!

Update with two “ad-hoc” solutions, one being more workable than the other.

  • Full Disclosure: I entered appropriate prompts into “Google Search” and let Google’s AI offer a solution. It took 6 iterations of refining the query text as a single “search” submission before getting to what I got.


Solution 1 - Full Manual Interactive Prompting

  • (Considered by me to be most practical, at this time, although requires too much interractive time. :frowning: )

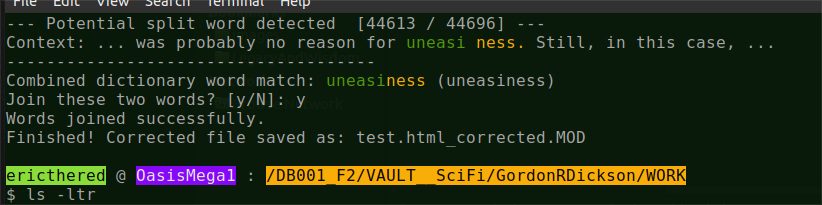
  • (Note that I directed the two candidate word segments to be coloured as green and orange, in order to make them stand out more. :slight_smile: I also added the “progress index” at the end of that top line, to get a visual sense of progress. )

Snapshot of end of session, showing the interractive “TUI”:

Script for Solution 1
#!/bin/bash

#############################################################################################
#
# Date: 2026-09-20
# Released into public domain by query originator, Eric Marceau, Ottawa, Canada
#
#############################################################################################
#
# Auto-generated as a Google Search response to the following query text:
#
#	Linux is there a spelling tool that can be used for stepwise advancing
#	thru a text and comparing two consecutive strings to identify possible
#	matches of the joined pair forming a dictionary word and prompting the
#	user to confirm removing the white space separating the two strings?
#	Do not offer a solution using Python. Use only common Linux libraries
#	and utilities to perform the desired function, and offer a script to
#	call the actions. When prompting with the context, present 5 context
#	strings before and after the pair being evaluated.  Ensure that the
#	provided script presents the string contained by the first of the join
#	candidate word is highlighted in green and the string contained by
#	the second candidate word is highlighted in orange.
#
#############################################################################################

# Path to the system dictionary
DICTIONARY="/usr/share/dict/words"

# Verify dictionary exists
if [ ! -f "$DICTIONARY" ]; then
    echo "Error: System dictionary not found at $DICTIONARY."
    echo "Please install it (e.g., 'sudo apt install wamerican' or 'sudo yum install words')."
    exit 1
fi

# Verify input file
if [ -z "$1" ] || [ ! -f "$1" ]; then
    echo "Usage: $0 <text_file>"
    exit 1
fi

INPUT_FILE="$1"

# ANSI Color codes
GREEN="\e[32m"
ORANGE="\e[38;5;214m" # 256-color orange
RESET="\e[0m"

# Read the file into an array of words
# This removes line breaks and stores punctuation attached to words.
# To clean punctuation for matching while retaining it for display, we strip it during dictionary lookup.
words=( $(cat "$INPUT_FILE") )
num_words=${#words[@]}

i=0
while [ $i -lt $((num_words - 1)) ]; do
    word1="${words[$i]}"
    word2="${words[$((i+1))]}"
    
    # Strip common trailing/leading punctuation for strict dictionary comparison
    clean1=$(echo "$word1" | tr -d '[:punct:]')
    clean2=$(echo "$word2" | tr -d '[:punct:]')
    joined="${clean1}${clean2}"
    
    # Check if the lowercased joined string exists as a whole word in the dictionary
    if [ -n "$joined" ] && grep -Fxq "${joined,,}" "$DICTIONARY"; then
        clear
        echo "--- Potential split word detected  [${i} / ${num_words}] ---"
        echo -n "Context: ... "
        
        # Print up to 5 words of preceding context
        start_ctx=$(( i - 5 ))
        [ $start_ctx -lt 0 ] && start_ctx=0
        for ((c=start_ctx; c<i; c++)); do
            echo -n "${words[$c]} "
        done
        
        # Print the highlighted candidate pair
        echo -n -e "${GREEN}${word1}${RESET} ${ORANGE}${word2}${RESET}"
        
        # Print up to 5 words of succeeding context
        end_ctx=$(( i + 6 ))
        [ $end_ctx -gt $num_words ] && end_ctx=$num_words
        for ((c=i+2; c<end_ctx; c++)); do
            echo -n " ${words[$c]}"
        done
        echo " ..."
        echo "-------------------------------------"
        echo -e "Combined dictionary word match: ${GREEN}${clean1}${ORANGE}${clean2}${RESET} (${joined,,})"
        
        # Prompt user for replacement
        read -p "Join these two words? [y/N]: " choice
        case "$choice" in
            [yY][eE][sS]|[yY])
                # Join word1 and word2 directly into word1's index position
                words[$i]="${word1}${word2}"
                # Remove word2's entry from the array by shifting elements
                for ((j=i+1; j<num_words-1; j++)); do
                    words[$j]="${words[$((j+1))]}"
                done
                unset "words[$((num_words-1))]"
                ((num_words--))
                echo "Words joined successfully."
                # Re-evaluate the new joined string against the next word
                continue 
                ;;
            *)
                echo "Skipped."
                ;;
        esac
    fi
    ((i++))
done

# Save the modifications back to a new file or overwrite
OUTPUT_FILE="${INPUT_FILE%.*}_corrected.${INPUT_FILE##*.}"
echo "${words[*]}" > "$OUTPUT_FILE"
echo "Finished! Corrected file saved as: $OUTPUT_FILE"


Solution 2 - 2-Phase, Partly-automated, partly Manual Interactive Prompting

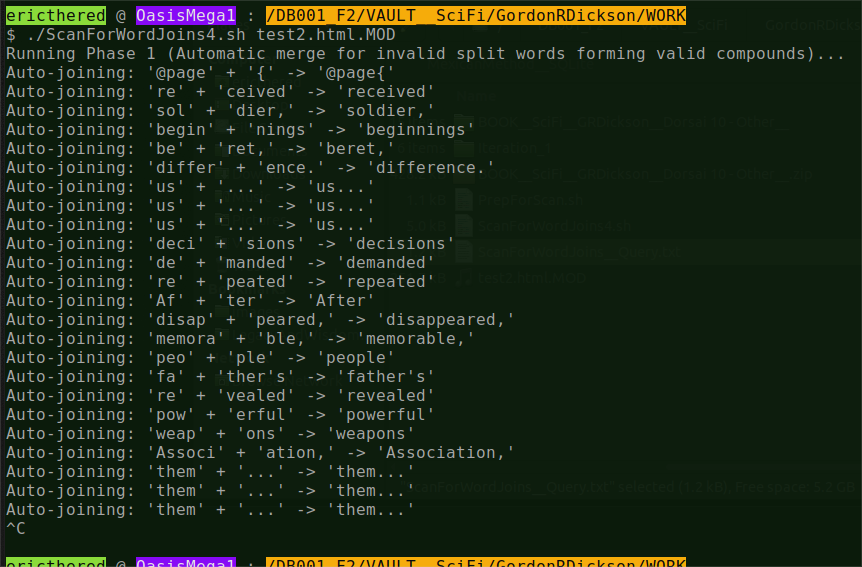
  • (Considered by me to be impractical because the automated phase is much too time-consuming! :frowning: Also needs logic modified to skip some pattern instances, such as the “…” and similar non-word patterns.)

  • ( Phase II involved logic similar to that found in Solution 1)

Snapshot of the partial session involving Phase I

Script for Solution 2
#!/usr/bin/env bash

#############################################################################################
#
# Date: 2026-09-20
# Released into public domain by query originator, Eric Marceau, Ottawa, Canada
#
#############################################################################################
#
# Auto-generated as a Google Search response to the following query text:
#
#	Linux is there a spelling tool that can be used for stepwise advancing
#	thru a text and comparing two consecutive strings to identify possible
#	matches of the joined pair forming a dictionary word and prompting the
#	user to confirm removing the white space separating the two strings?
#	Do not offer a solution using Python. Use only common Linux libraries
#	and utilities to perform the desired function, and offer a script to
#	call the actions. When prompting with the context, present 5 context
#	strings before and after the pair being evaluated.  Ensure that the
#	provided script presents the string contained by the first of the join
#	candidate word is highlighted in green and the string contained by
#	the second candidate word is highlighted in orange.
#
#	The script should perform the manipulation in two phases, the first
#	phase where either of the string pairs is not a recognized dictionary
#	word, but the joined pair is such a recognized dictionary word. This
#	first phase would be performed without prompting.  The second phase
#	would be performed with prompting, as per the initial problem statement,
#	for the remaining instances where both words are recognized dictionary words.
#
#############################################################################################

# Check input file
INPUT_FILE="$1"
if [ -z "$INPUT_FILE" ] || [ ! -f "$INPUT_FILE" ]; then
    echo "Usage: $0 <text_file>"
    exit 1
fi

# Define the dictionary source. Fallback to /usr/share/dict/words if hunspell is not present.
check_word() {
    local word=$(echo "$1" | tr -d '[:punct:][:space:]')
    [ -z "$word" ] && return 1
    if command -v hunspell >/dev/null 2>&1; then
        # hunspell -a outputs an asterisk (*) if the word is correct
        echo "$word" | hunspell -a | grep -q '^*'
    else
        grep -Fxiq "$word" /usr/share/dict/words
    fi
}

# ANSI Color Codes
GREEN='\033[0;32m'
ORANGE='\033[0;33m' # Standard 8-color ANSI Brown/Orange
RESET='\033[0m'

# Temporary files to store iterations
TMP_PHASE1=$(mktemp)
TMP_PHASE2=$(mktemp)
cp "$INPUT_FILE" "$TMP_PHASE1"

# --- PHASE 1: AUTOMATIC MANIPULATION ---
echo "Running Phase 1 (Automatic merge for invalid split words forming valid compounds)..."
while true; do
    # Read words into an array
    words=( $(cat "$TMP_PHASE1") )
    len=${#words[@]}
    changed=0
    
    for ((i=0; i<len-1; i++)); do
        w1="${words[i]}"
        w2="${words[i+1]}"
        joined="${w1}${w2}"
        
        # Strip punctuation for spelling checks
        w1_clean=$(echo "$w1" | tr -d '[:punct:]')
        w2_clean=$(echo "$w2" | tr -d '[:punct:]')
        joined_clean=$(echo "$joined" | tr -d '[:punct:]')
        
        # Condition: joined is valid AND (w1 is invalid OR w2 is invalid)
        if check_word "$joined_clean"; then
            if ! check_word "$w1_clean" || ! check_word "$w2_clean"; then
                echo "Auto-joining: '$w1' + '$w2' -> '$joined'"
                
                # Rebuild text up to this point and perform the merge
                # We use a precise awk substitution to merge the first matching instance
                awk -v w1="$w1" -v w2="$w2" -v j="$joined" '
                    BEGIN {done=0}
                    {
                        if (!done && match($0, w1 "[[:space:]]+" w2)) {
                            $0 = substr($0, 1, RSTART-1) j substr($0, RSTART+RLENGTH)
                            done = 1
                        }
                        print
                    }
                ' "$TMP_PHASE1" > "${TMP_PHASE1}.tmp" && mv "${TMP_PHASE1}.tmp" "$TMP_PHASE1"
                
                changed=1
                break # Break out to reread array with updated positions
            fi
        fi
    done
    [ $changed -eq 0 ] && break
done

cp "$TMP_PHASE1" "$TMP_PHASE2"

# --- PHASE 2: INTERACTIVE MANIPULATION ---
echo -e "\nRunning Phase 2 (Interactive merge for dual-valid words)..."
while true; do
    words=( $(cat "$TMP_PHASE2") )
    len=${#words[@]}
    changed=0
    
    for ((i=0; i<len-1; i++)); do
        w1="${words[i]}"
        w2="${words[i+1]}"
        joined="${w1}${w2}"
        
        w1_clean=$(echo "$w1" | tr -d '[:punct:]')
        w2_clean=$(echo "$w2" | tr -d '[:punct:]')
        joined_clean=$(echo "$joined" | tr -d '[:punct:]')
        
        # Condition: BOTH w1 and w2 are valid, AND joined is also valid
        if check_word "$w1_clean" && check_word "$w2_clean" && check_word "$joined_clean"; then
            echo -e "\n--------------------------------------------------"
            echo -e "Possible joined word candidate detected!"
            
            # Context window indices (5 before, 5 after)
            start_ctx=$(( i - 5 < 0 ? 0 : i - 5 ))
            end_ctx=$(( i + 6 > len - 1 ? len - 1 : i + 6 ))
            
            # Print Context
            printf "Context: ... "
            for ((j=start_ctx; j<=end_ctx; j++)); do
                if [ $j -eq $i ]; then
                    printf "${GREEN}%s${RESET} " "${words[j]}"
                elif [ $j -eq $((i+1)) ]; then
                    printf "${ORANGE}%s${RESET} " "${words[j]}"
                else
                    printf "%s " "${words[j]}"
                fi
            done
            printf "...\n"
            
            # Prompt User
            read -p "Join '${w1}' and '${w2}' into '${joined}'? [y/N]: " ans
            if [[ "$ans" =~ ^[Yy]$ ]]; then
                awk -v w1="$w1" -v w2="$w2" -v j="$joined" '
                    BEGIN {done=0}
                    {
                        if (!done && match($0, w1 "[[:space:]]+" w2)) {
                            $0 = substr($0, 1, RSTART-1) j substr($0, RSTART+RLENGTH)
                            done = 1
                        }
                        print
                    }
                ' "$TMP_PHASE2" > "${TMP_PHASE2}.tmp" && mv "${TMP_PHASE2}.tmp" "$TMP_PHASE2"
                
                changed=1
                break
            fi
        fi
    done
    [ $changed -eq 0 ] && break
done

# Save back to final file
OUTPUT_FILE="${INPUT_FILE%.*}_corrected.${INPUT_FILE##*.}"
cp "$TMP_PHASE2" "$OUTPUT_FILE"
rm -f "$TMP_PHASE1" "$TMP_PHASE2"

echo -e "\nProcessing Complete! Corrected text saved to: ${OUTPUT_FILE}"